High-throughput computing with GROMACS
Note
High-throughput simulations can easily produce a lot of data, so please plan your data management (data flow, storage needs) and analysis pipelines beforehand. Don't hesitate to contact CSC Service Desk if you're unsure about any aspect of your workflow.
GROMACS comes with a built-in multidir
functionality, which allows users to run multiple concurrent simulations within
one Slurm allocation. This is an excellent option for high-throughput use
cases, where the aim is to run several similar, but independent, jobs. Notably,
multiple calls of sbatch or srun are not needed, which decreases the load
on the batch queue system. Please consider this option if you're running
high-throughput workflows or enhanced sampling jobs such as replica exchange or
free energy simulations using ensemble-based distance or orientation
restraints.
Another utility of multidir is that it can be used to increase the parallel
efficiency of small systems. By launching multiple trajectories per GPU (or CPU
node), the combined throughput of each independent simulation will increase due
to better resource utilization. This is especially useful for maximizing the
performance of small systems on Roihu-GPU and LUMI-G.
Example batch scripts
This example adapts the production part of the
lysozyme tutorial by
considering 8 similar copies of the system that have been equilibrated with
different velocity initializations. Inputs corresponding to each copy are
named identically md_0_1.tpr and placed in subdirectories run* as
illustrated below by the output of the tree command.
$ tree
.
├── multidir.sh
├── run1
│   └── md_0_1.tpr
├── run2
│   └── md_0_1.tpr
├── run3
│   └── md_0_1.tpr
├── run4
│   └── md_0_1.tpr
├── run5
│   └── md_0_1.tpr
├── run6
│   └── md_0_1.tpr
├── run7
│   └── md_0_1.tpr
└── run8
    └── md_0_1.tpr
#!/bin/bash
#SBATCH --time=00:30:00
#SBATCH --partition=medium
#SBATCH --account=<project>
#SBATCH --nodes=1
#SBATCH --ntasks-per-node=384

# this script runs a 384 core GROMACS multidir job
# (8 simulations, 48 cores per simulation)

module purge
module load gromacs-env

export OMP_NUM_THREADS=1

srun gmx_mpi mdrun -multidir run* -s md_0_1.tpr -dlb yes
By issuing sbatch multidir.sh in the parent directory, all simulations
are run concurrently using one full Roihu-CPU node without hyperthreading
so that each system is allocated 48 cores. As the systems were initialized
with different velocities, we obtain 8 distinct trajectories and an
improved sampling of the phase space (see RMSD analysis below). This is a
great way to accelerate sampling if your system does not scale to a full
Roihu-CPU node.

Large systems (>1 million atoms) are typically able to utilize multiple GPUs efficiently. Many smaller use cases may also run well on a single GPU, but the smaller a system gets, the poorer it will be able to utilize the full capacity of the accelerator.
The multidir feature can be used to increase the GPU utilization of small
systems by running multiple trajectories per GPU. Below is an example batch
script that launches 8 trajectories per GPU in a full-node Roihu-GPU job (4
GPUs). Each of the 32 .tpr files is named identically as topol.tpr and
organized into separate directories run1 through run32, similar to the
Roihu-CPU example.
CUDA Multi-Process Service
It is mandatory to use the CUDA Multi-Process Service (MPS) to allow multiple MPI processes using CUDA to run concurrently on a single GPU on Roihu. See the batch script below for an example on usage.
#!/bin/bash
#SBATCH --time=00:15:00
#SBATCH --partition=gpumedium
#SBATCH --account=<project>
#SBATCH --nodes=1
#SBATCH --ntasks-per-node=32
#SBATCH --cpus-per-task=9
#SBATCH --gres=gpu:gh200:4

module purge
module load gromacs-env

export OMP_NUM_THREADS=${SLURM_CPUS_PER_TASK}
export GMX_ENABLE_DIRECT_GPU_COMM=1
export GMX_FORCE_GPU_AWARE_MPI=1

# NVIDIA CUDA Multi-Process Service (MPS) required to run multiple tasks per GPU
nvidia-cuda-mps-control -d

srun gmx_mpi mdrun -s topol -nb gpu -bonded gpu -pme gpu -update gpu -multidir run*

echo quit | nvidia-cuda-mps-control
Note that the number of MPI tasks you request must be a multiple of the number of independent inputs, in this case 1 task per input. Since there are 72 CPU cores available per Roihu GPU, we use 9 threads per task.
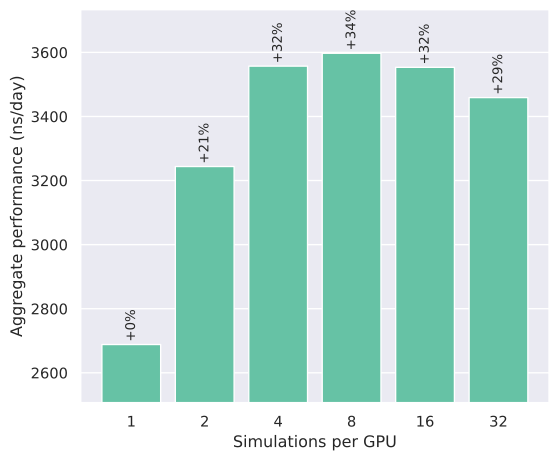
The plot below shows the total combined throughput obtained when running multiple replicas of the 96k atom alcohol dehydrogenase (ADH) benchmark on a full Roihu-GPU node (2 fs timestep). When the number of trajectories per GPU is increased from 1 to 8, the aggregate performance (sum of each independent trajectory) increases by about 34% due to better GPU utilization. Since each simulation is independent, one could scale this use case to a huge number of nodes for maximal throughput.
The example below launches 7 trajectories per MI250X GCD in a full-node
LUMI-G job (8 GCDs). Each .tpr file is organized into separate
directories run1 through run56, similar to the Roihu-GPU example.
#!/bin/bash
#SBATCH --time=01:00:00
#SBATCH --partition=standard-g
#SBATCH --account=<project>
#SBATCH --nodes=1
#SBATCH --gpus-per-node=8
#SBATCH --ntasks-per-node=56

module use /appl/local/csc/modulefiles
module load gromacs/2026.1-gpu

export OMP_NUM_THREADS=1
export MPICH_GPU_SUPPORT_ENABLED=1
export GMX_ENABLE_DIRECT_GPU_COMM=1
export GMX_FORCE_GPU_AWARE_MPI=1

cat << EOF > select_gpu
#!/bin/bash

export ROCR_VISIBLE_DEVICES=\$((SLURM_LOCALID%SLURM_GPUS_PER_NODE))
exec \$*
EOF

chmod +x ./select_gpu

CPU_BIND="mask_cpu:fe000000000000,fe00000000000000"
CPU_BIND="${CPU_BIND},fe0000,fe000000"
CPU_BIND="${CPU_BIND},fe,fe00"
CPU_BIND="${CPU_BIND},fe00000000,fe0000000000"

srun --cpu-bind=${CPU_BIND} ./select_gpu gmx_mpi mdrun -s topol -nb gpu -bonded gpu -pme gpu -update gpu -multidir run*
Note that the number of MPI tasks you request must be a multiple of the number of independent inputs, in this case 1 task per input. Since there are only 56 CPU cores available per LUMI-G node, we use a single thread per task.
CPU-GPU binding on LUMI
For details on CPU-GPU binding, see the GROMACS application page, as well as the LUMI user guide.
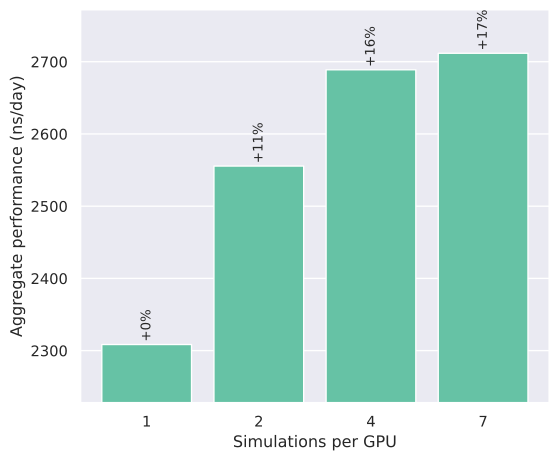
The plot below shows the total combined throughput obtained when running multiple replicas of the 96k atom alcohol dehydrogenase (ADH) benchmark on a single LUMI-G node (2 fs timestep). When the number of trajectories per GCD is increased from 1 to 7, the aggregate performance (sum of each independent trajectory) increases by about 17% due to better GPU utilization. Since each simulation is independent, one could scale this use case to a huge number of nodes for maximal throughput.